---
base_model: Qwen/Qwen-Image-2.1
tags:
- fp8
- int8
- unsloth
- quantized
- diffusers
- qwen
- image-generation
- image-editing
- rgba
- text-to-image
license: other
license_name: qwen-research
license_link: https://huggingface.co/Qwen/Qwen-Image-2.1/blob/main/LICENSE
language:
- en
- zh
library_name: diffusers
pipeline_tag: text-to-image
widget:
- text: Photorealistic photograph of an old movie theater with faded red seats, peeling walls, and a torn screen.
output:
url: samples/int8_2.png
- text: A rally car speeding across vast desert dunes, throwing a dramatic trail of sand behind it.
output:
url: samples/fp8_1.png
- text: Photorealistic editorial photograph of a woman barista making a latte in a modern, minimalist café on a sunny tropical morning.
output:
url: samples/int8_1.png
- text: A lone astronaut crossing a dark, frozen lake beneath enormous rings stretching across an alien sky. Fine cracks visible under the translucent ice, distant mountains, soft blue twilight, cinematic scale, photorealistic detail.
output:
url: samples/fp8_2.png
---
# Read our How to [Run Qwen-Image-2.1 Guide!](https://unsloth.ai/docs/models/qwen-image-2.1) 💜
This is an FP8 / INT8 quantized version of [Qwen-Image-2.1](https://huggingface.co/Qwen/Qwen-Image-2.1), plus a pre-cast FP8 copy of its Qwen3-VL text encoder.
- For higher quality, you can also run Dynamic FP8 on just 6GB of VRAM via offloading (<2x slower).
- Optimized for efficient inference with reduced memory footprint. Same-seed LPIPS vs the bf16 model (lower is better): 0.064 INT8, 0.112 FP8. INT8 is the shipped scheme.
- In [Unsloth Desktop](https://github.com/unslothai/unsloth) these are used automatically: pick Qwen-Image-2.1 and an INT8 or FP8 precision.
| file | size | replaces |
|---|---|---|
| `Qwen-Image-2.1-INT8.safetensors` | 7.26 GB | the 14.23 GB bf16 `transformer` |
| `Qwen-Image-2.1-FP8.safetensors` | 7.12 GB | the 14.23 GB bf16 `transformer` |
| `Qwen-Image-2.1-text_encoder-FP8.safetensors` | 9.39 GB | the 17.5 GB bf16 `text_encoder` |
| `vae/qwen_image_2.1_vae_bf16.safetensors` | 0.63 GB | the fp32 `vae`, for [unsloth/Qwen-Image-2.1-GGUF](https://huggingface.co/unsloth/Qwen-Image-2.1-GGUF) |
Everything here is safetensors rather than a pickle, so loading runs no arbitrary code. Needs a diffusers main build: Qwen-Image-2.1 support postdates the 0.40 release.
---
### Samples
---
🤖 ModelScope |
🤗 HuggingFace |
📑 Blog |
🖥️ Demo |
🫨 Discord |
💬 WeChat
## Introduction
We are excited to open-source **Qwen-Image-2.1**, a unified text-to-image generation and image editing model in the Qwen family. With just **7B parameters in its visual generation component** (32 Single-Stream DiT layers), Qwen-Image-2.1 balances generation quality, inference efficiency, and versatility.
Four key improvements define this release:
- **Compact and Efficient**: a lightweight architecture with mixed-granularity attention and prefix KV cache reuse delivers strong image quality at low computational cost.
- **Native Transparency, Unified Creation and Editing**: generate regular or transparent (RGBA) images from text, edit transparent layers, and extract subjects from photographs, all in one model.
- **Versatile Editing**: support up to **10 reference images**, specify local edits via circles, painted annotations, or separate masks, and preserve identity for people and products.
- **Realistic Textures and Refined Aesthetics**: improved typography, portrait lighting, and fine details for more visually compelling results.
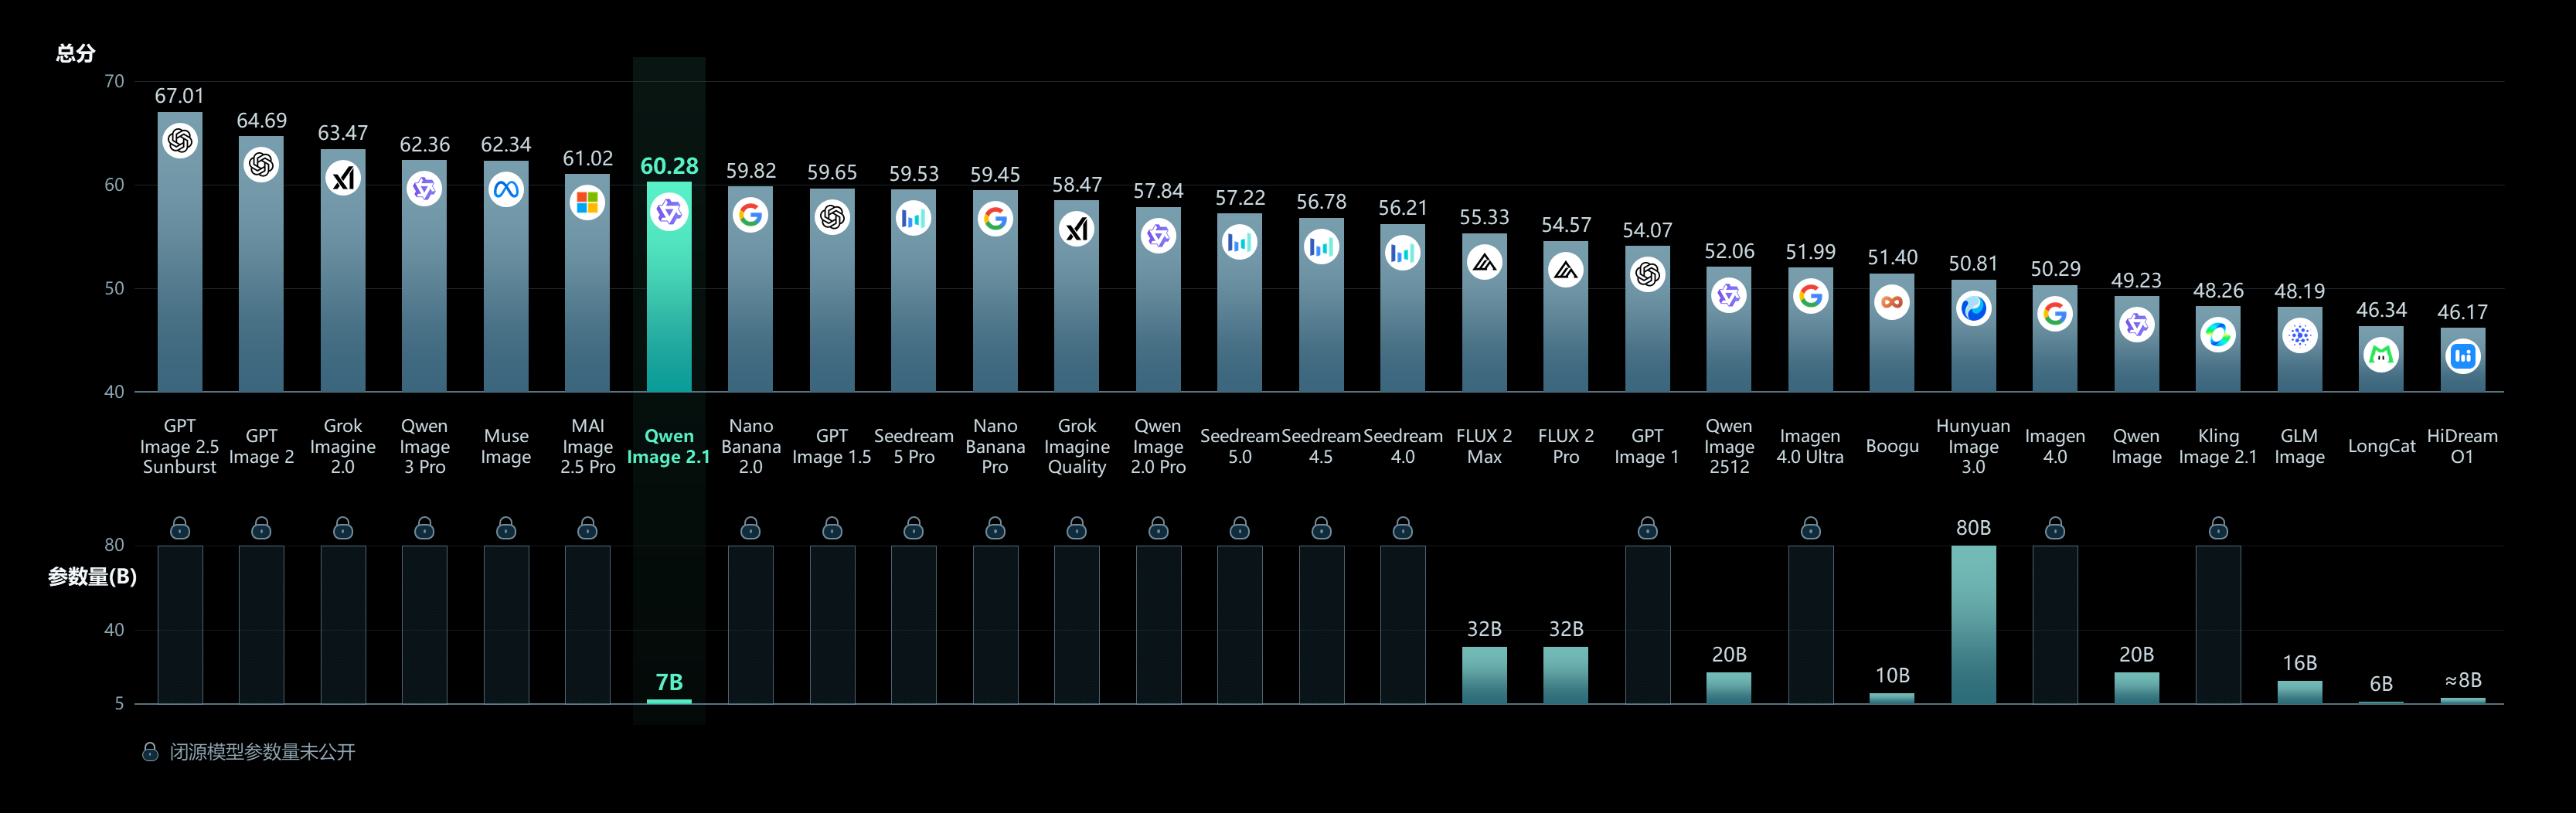
For more details, see the [GitHub repo](https://github.com/QwenLM/Qwen-Image-2.1) and [Blog](https://qwen.ai/blog?id=qwen-image-2.1).
## Quick Start
### Installation
```bash
pip install torch>=2.4.0
pip install transformers>=5.17
pip install git+https://github.com/huggingface/diffusers
pip install accelerate pillow
```
### Text-to-Image
```python
import torch
from diffusers import QwenImage21Pipeline
pipe = QwenImage21Pipeline.from_pretrained(
"Qwen/Qwen-Image-2.1", torch_dtype=torch.bfloat16
).to("cuda")
image = pipe(
prompt="A neon shop sign that reads \"QWEN IMAGE 2.1\", rainy night, reflections on wet pavement",
width=2048, height=2048,
num_inference_steps=40,
generator=torch.Generator("cuda").manual_seed(42),
).images[0]
image.save("t2i_example.png")
```
### Image Editing
```python
import torch
from PIL import Image
from diffusers import QwenImage21Pipeline
pipe = QwenImage21Pipeline.from_pretrained(
"Qwen/Qwen-Image-2.1", torch_dtype=torch.bfloat16
).to("cuda")
input_image = Image.open("input.png")
image = pipe(
prompt="Change the background to a sunset beach",
image=input_image,
num_inference_steps=40,
generator=torch.Generator("cuda").manual_seed(42),
).images[0]
image.save("edit_example.png")
```
### Transparent Image Generation (RGBA)
Use the recommended prompt format for transparent images:
```python
image = pipe(
prompt="This is an RGBA image with transparency. A cute cartoon dragon sticker. The image has alpha channel and the background is transparent.",
width=2048, height=2048,
num_inference_steps=40,
generator=torch.Generator("cuda").manual_seed(42),
).images[0]
image.save("transparent_example.png")
```
### Supported Aspect Ratios
```python
aspect_ratios = {
"1:1": (2048, 2048),
"4:3": (2400, 1792),
"3:4": (1792, 2400),
"3:2": (2528, 1696),
"2:3": (1696, 2528),
"16:9": (2752, 1536),
"9:16": (1536, 2752),
}
```
### Memory Optimization
```python
pipe = QwenImage21Pipeline.from_pretrained(
"Qwen/Qwen-Image-2.1", torch_dtype=torch.bfloat16
)
pipe.enable_model_cpu_offload()
```
## Showcase
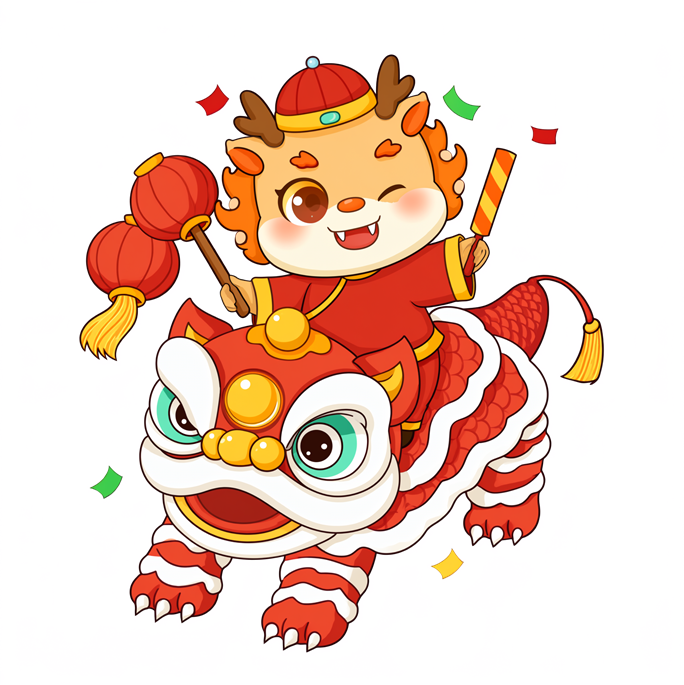
Native transparent image generation
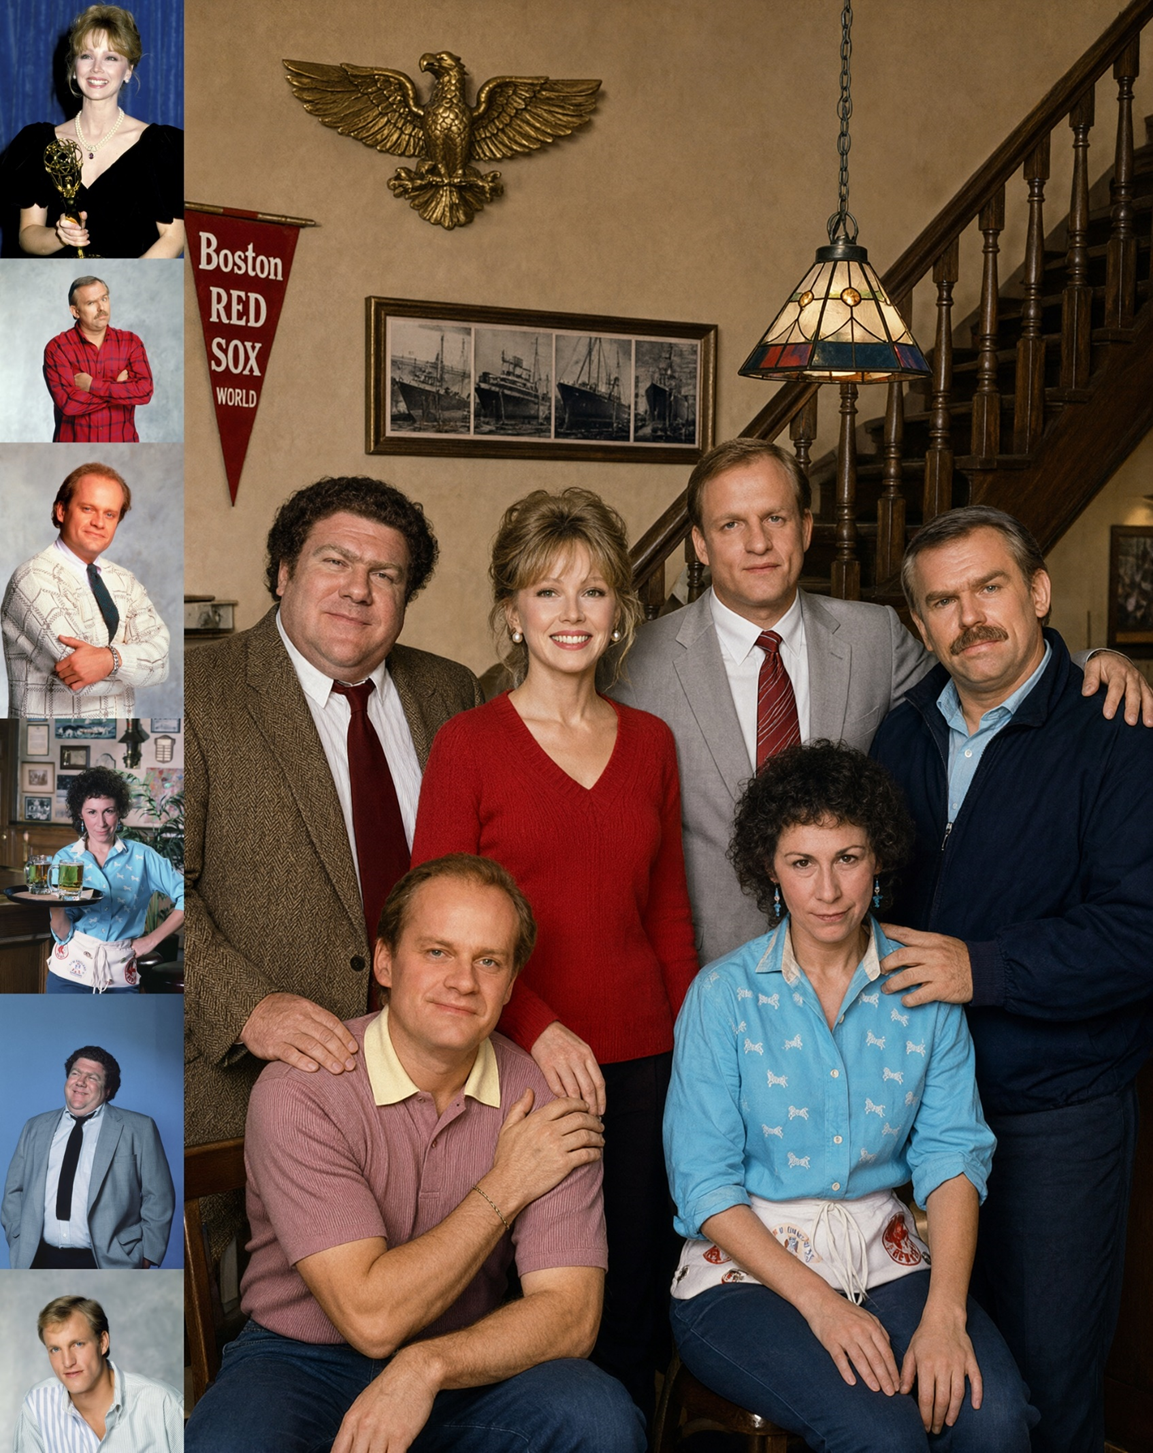
Group photograph generated from six portrait references
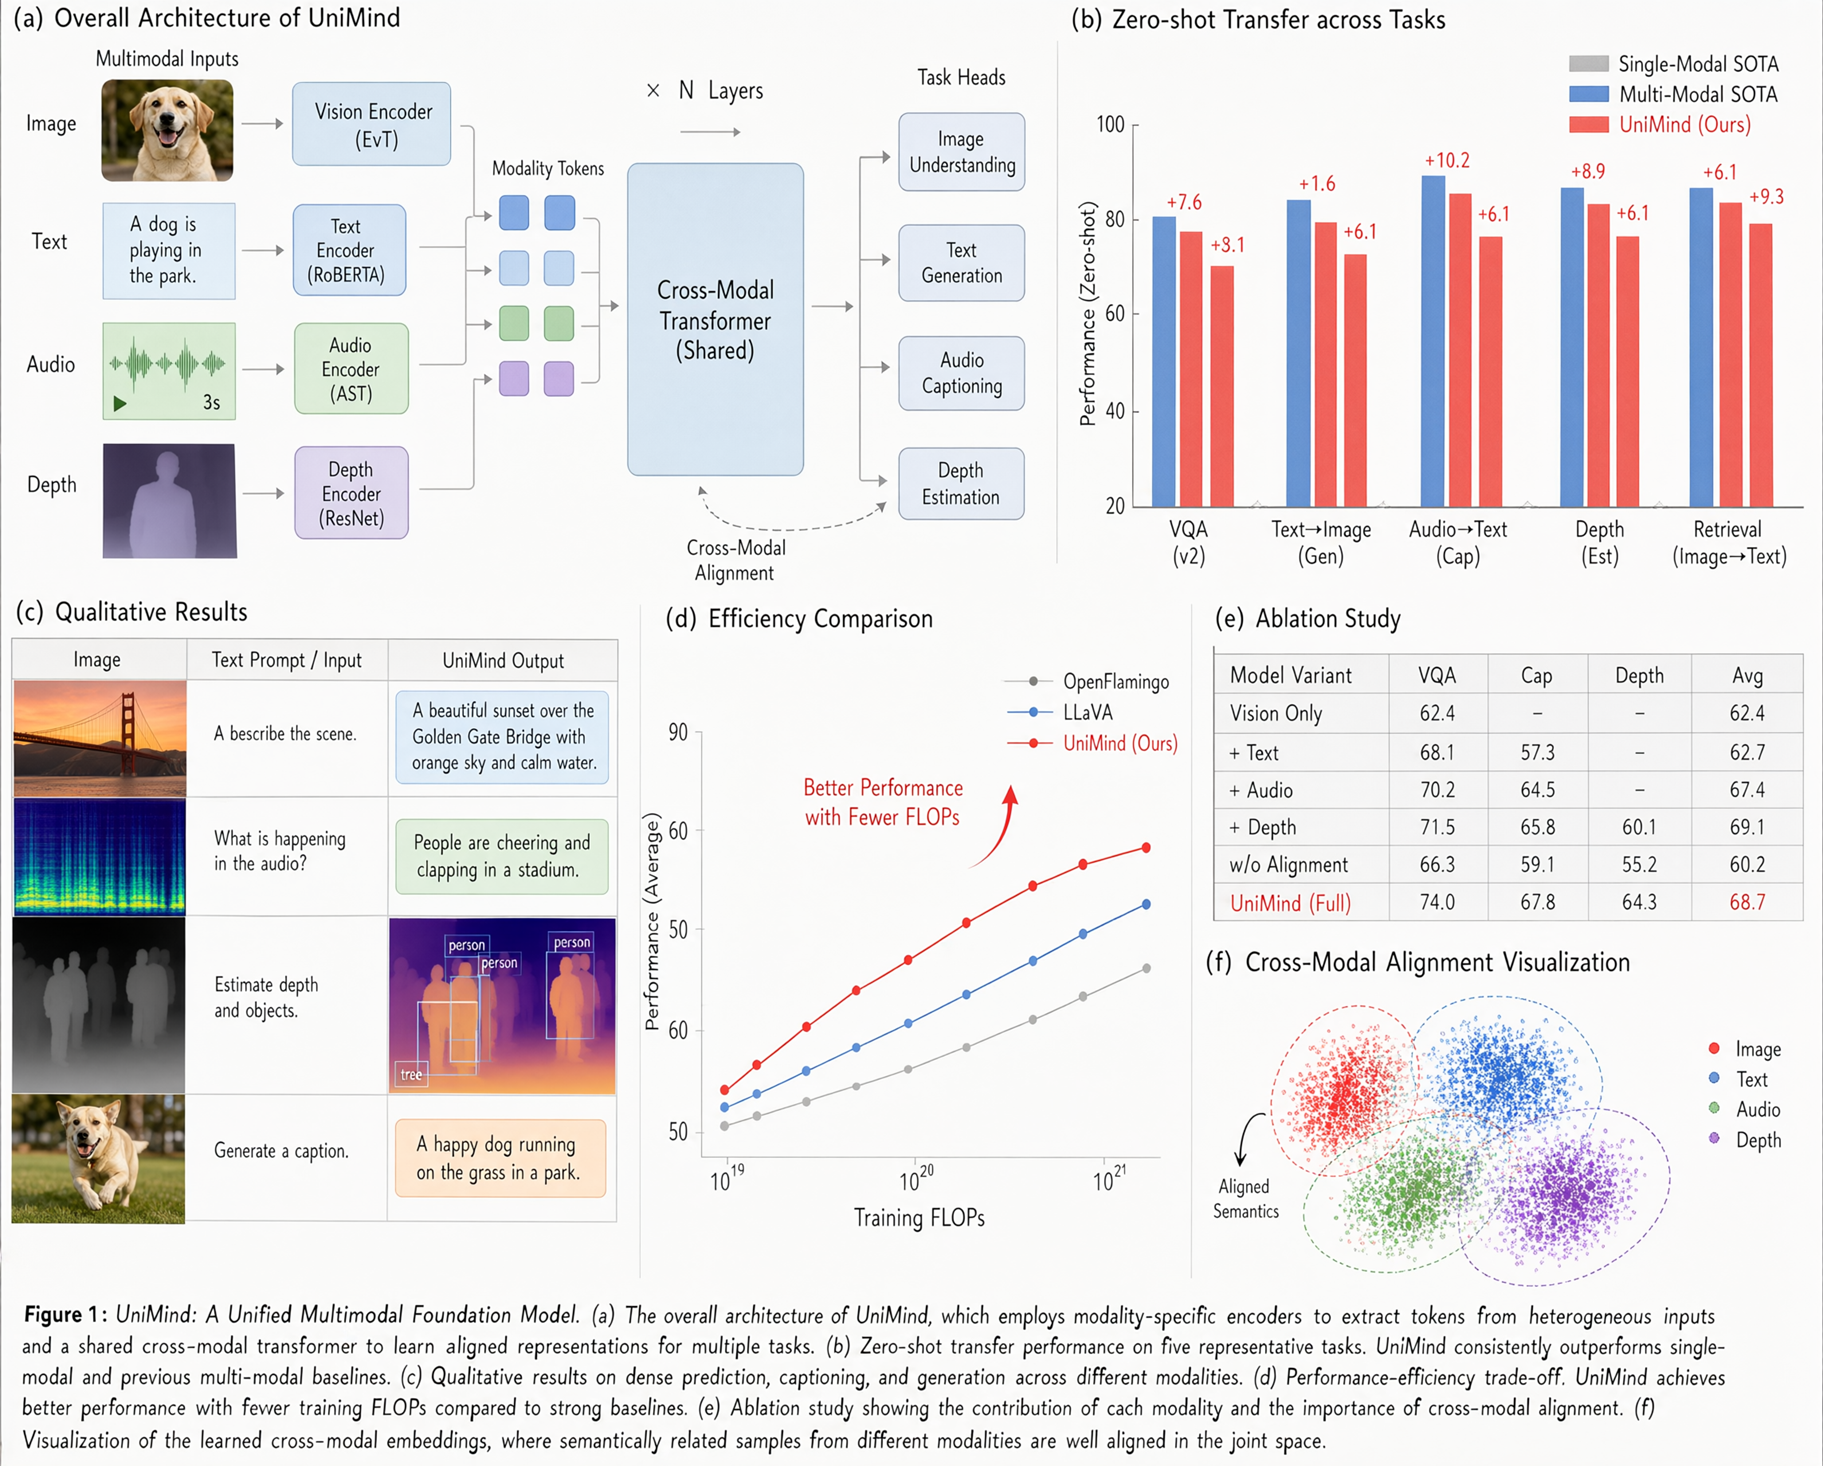
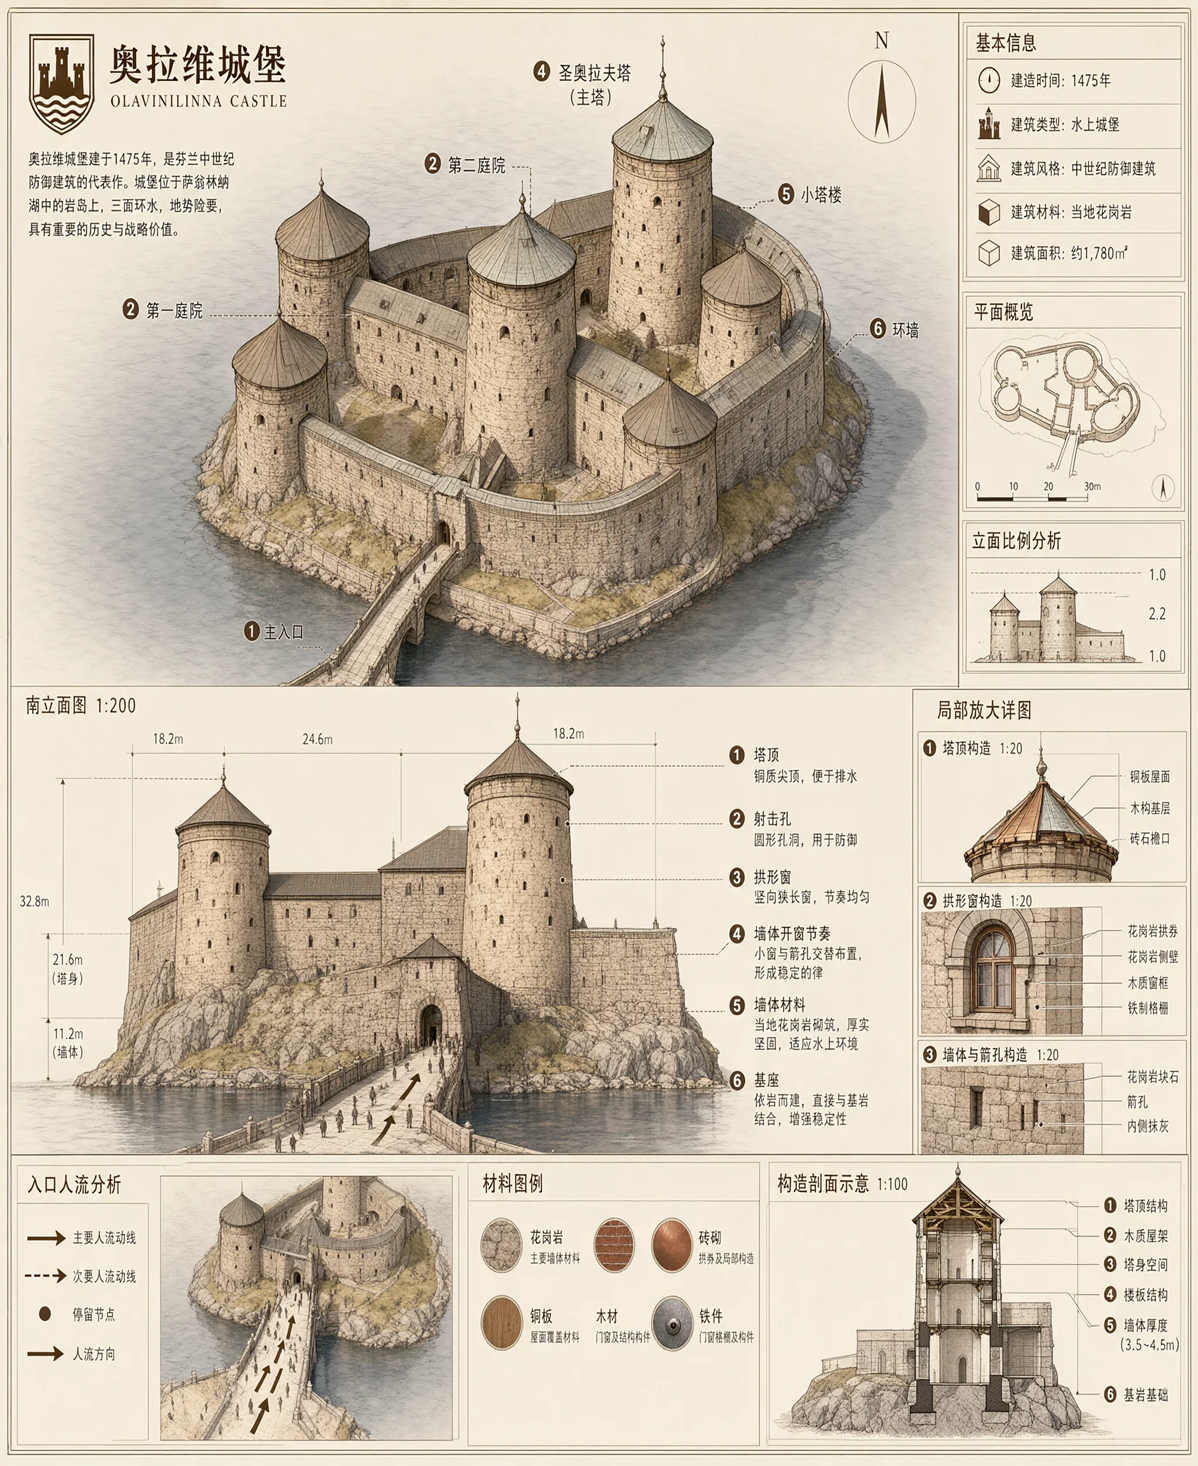
Text rendering
## License
This model is licensed under the [Qwen Research License Agreement](https://huggingface.co/Qwen/Qwen-Image-2.1/blob/main/LICENSE).